Nine Empty Fields in an Athletics Report: Why Missing Data Is Not Clean Data
**Câu trả lời cốt lõi:** Bản phân tích điền kinh có cấu trúc đầy đủ nhưng thiếu toàn bộ điểm thông tin đầu vào. Kết quả rỗng không đồng nghĩa với kết luận sạch: không có dữ kiện doping không phải là không có rủi ro doping, và mọi kết luận cần điểm neo ở tầng dữ kiện gốc. **Dữ kiện chính:** - Nhãn duy nhất còn dùng được trong tệp dữ kiện gốc là lĩnh vực điền kinh; tiêu đề, nguồn, tóm tắt và tập điểm thông tin đều trống. - Chỉ số gió hợp lệ cho kỷ lục là tối đa 2,0 mét trên giây; sân trên 1.000 mét so với mực nước biển cần được hiệu chỉnh riêng. - World Athletics áp giới hạn đế giày đường chạy 40 milimét và một tấm đế cứng từ ngày 30 tháng 4 năm 2020. - Sàng lọc tăng tiến thành tích: bước nhảy vượt khoảng ba lần mức tăng thường niên của chính vận động viên thuộc diện kiểm tra. - Không có nội dung doping trong một bài phân tích không được báo cáo thành không có rủi ro doping. **Nguồn:** Bản phân tích chuyên sâu tầng hai, lĩnh vực điền kinh (tài liệu nội bộ, không ghi ngày phát hành) | Đối chiếu: VuaBong.vn **Hỏi đáp liên quan:** - Hỏi: Vì sao một tệp phân tích rỗng lại nguy hiểm? Đáp: Vì khoảng trống dữ liệu thường bị lấp bằng suy diễn, và người đọc dễ hiểu nhầm kết quả rỗng thành kết luận an toàn. - Hỏi: Cần tối thiểu những dữ kiện nào để phân tích một thành tích điền kinh? Đáp: Tên nội dung, thành tích kèm chỉ số gió, độ cao sân, vòng thi đấu, thứ hạng và kênh vượt vòng loại tương ứng. - Hỏi: Chỉ số VangBong.vn Player Depth Index có thay thế được dữ liệu điền kinh không? Đáp: Không; chỉ số này đo chiều sâu đội hình bóng đá, trong khi phân tích điền kinh cần chuỗi thành tích cá nhân theo thời gian.
The result file sat on the screen with nine major sections. Each section had a comparison table, a risk-flag column, a source-note line. In every cell that could hold a fact, the person filling it left the same sentence: insufficient information to assess.
The source article title was blank. The source article origin was blank. The article type was unclassified. The one-sentence summary was empty. The set of information points was empty. The entities involved had not been extracted. Time sensitivity had not been assessed. Source quality was undefined. The only field still usable was the domain label: athletics.
I sat in front of that file longer than an empty file deserves. Across nine years of recording sports data, from notebooks in a secondary-school classroom to the dense tables of Japanese athletics meets, I have met every kind of broken document: misaligned columns, duplicated figures, records labelled with the wrong event, athlete names misspelled in the headline itself. But an analysis structured well enough to look serious, and empty enough to support no judgement at all, is a rarer document.
The real point lies elsewhere. A null result is not a clean result.
In sports analysis, people fall into two reflexes when they hit a data gap. The first reflex is to fill. The writer reaches for memory, for general impression, for whatever story is circulating on social media, and drops it into the empty cell. The second reflex is to ignore. Readers see no doping facts and assume a clean athlete; no injury facts and assume sound fitness; no dispute facts and assume everything is normal. Both reflexes produce the same output: a conclusion with no basis, presented as though it had one.
Nine empty fields, therefore, are not a failure of process. They are a personality test for the profession.
A Map of What Is Missing
The analysis pipeline I use has two layers. The first layer decomposes the source article into discrete data units: title, origin, article type, domain label, one-sentence summary, author stance, article purpose, set of information points, entities named, time sensitivity, source quality. The second layer runs nine deep-analysis dimensions, from performance assessment to athlete condition, competition structure, the event landscape, rules and anti-doping, the training system, and the risk matrix.
The binding condition of the second layer is strict: every analysis must be anchored in the information points from the first layer. Without an anchor there is no analysis. When it meets a null value, the process is required to write insufficient information to assess rather than to speculate.
Some will ask why the standard must be this severe. The answer lies in what athletics is. This is a sport measured in the smallest units available: one hundredth of a second, one centimetre. One hundredth of a second is enough to change a placing, change a qualifying slot, change sponsorship value, change an entire career. When the unit of measurement is that small, every data gap becomes an opportunity to invent a difference.
I have seen this in its most primitive form. On the night of Russia 2026, I watched the data shatter in front of me.
I was seventeen then, still a school student, recording every match of the Japan national team at the World Cup in minute detail. Against Belgium, Japan lost 2-3 in the round of sixteen. The post-match table showed 55 percent possession. But touches inside the opponent penalty area numbered 7, against Belgium's 21. I wrote an analysis on a personal blog, based entirely on the numbers, arguing that pushing the line high in the closing minutes was a structural error rather than an accident. The post drew heavy criticism from a group of supporters. I kept my position, but I took away a different and more important lesson: if I had not had the touch count in the box, what would I have written?
I would have written about spirit. About character. About the moment.
That is exactly what an empty set of information points produces. It does not make the article empty. It makes the article switch to a different material, softer, harder to verify, and usually wrong in ways nobody detects for years.
The First Anchor Layer: Mark, Wind Reading and Altitude
The first dimension of the second layer is event and performance analysis. It is the heaviest dimension, because every other dimension depends on it.
For this dimension to run, the first layer must supply a minimum list. The name of the event and the specific technical element: block start, split pacing, release angle, approach run in the long jump. The exact mark. The wind reading if the event is a sprint or a jump. The altitude of the venue. The competition name, the round, the placing. The relevant world, Olympic, continental and national records. The qualifying standard for that season. The world lead on the date of competition.
If any item on that list is missing, the comparison loses its value.
The wind reading is the clearest example. World Athletics recognises a record only when assisting wind does not exceed 2.0 metres per second. A 9.79 with a 2.1 metres per second wind is not a record; it is a datum unusable for ranking purposes, though still usable for assessing form. If the analysis does not state the wind reading, the reader has no way of knowing whether two things of the same kind are being compared or two things of different kinds.
Altitude works the same way. At Mexico City in 2026, Bob Beamon long-jumped 8.90 metres. The wind reading was 2.0 metres per second, legal. But the venue sits at roughly 2,240 metres above sea level. At that altitude air resistance falls, and sprint, long jump and triple jump events all receive a not insignificant benefit. That record stood for almost 23 years, and throughout that period analysts always had to attach an altitude note whenever they cited it. Without that note, the mark becomes a false statement about physics.
Then there is equipment. On 30 April 2026, World Athletics imposed technical limits on competition shoes: road racing shoes may not exceed 40 millimetres in sole thickness and may contain only one rigid plate; track shoes may not exceed 25 millimetres. Distance records set before that date, in the era of unrestricted carbon-plated soles, carry a technology dividend that cannot be separated from the performance. A serious analysis must deduct that dividend before talking about an athlete's ability.
And finally, split data. In the 400 metres, the first 200 metres and the last 200 metres say more than the total time. Two athletes finishing in the same 45.20 may be running two completely different races: one distributing evenly, one spending everything early and breaking late. On total time they look identical. On split data they are at different levels of fitness, and the forecast for their next race differs entirely.
A medal means something only when it comes with its measurement conditions. Remove the conditions and the medal is still a medal, but it is no longer data.
The Progression Curve and the Escalation Screen
The second dimension is athlete condition. This is the dimension I consider most sensitive in professional-ethics terms, because it sits right on the border between analysis and accusation.
The personal progression curve is the first tool. Not a single mark, but a series of season bests across at least five consecutive seasons. That series shows whether an athlete is rising, plateauing, or entering decline.
Here the second layer needs an age reference frame. The peak-age bands commonly used in athletics analysis are: sprint events roughly 24 to 29; middle and long distance roughly 26 to 31; throwing and pushing events roughly 28 to 33. I stress that these are statistical bands, not laws. The variance is large. Some sprinters peak at 21 and some at 33. Using these bands to exclude is wrong; using them to ask questions is right.
The second tool is the progression screen. The working rule is this: if a single year's gain exceeds roughly three times the athlete's own historical annual gain, the case belongs on an investigation list, not a conclusion list. I have to state that boundary clearly, because the profession has a bad habit of turning a statistical anomaly into a verdict. An abnormal jump can come from a coaching change, a schedule change, recovery from a long injury, a technical overhaul, or simply a small sample. It can also come from doping. The analyst's job is to flag, not to judge.
The third tool is injury and withdrawal history. An athlete who withdraws from competition in two or more consecutive seasons is a high-risk flag in my framework. The reason is not medical but probabilistic: a repeating withdrawal pattern makes every form forecast unstable and every performance comparison lopsided.
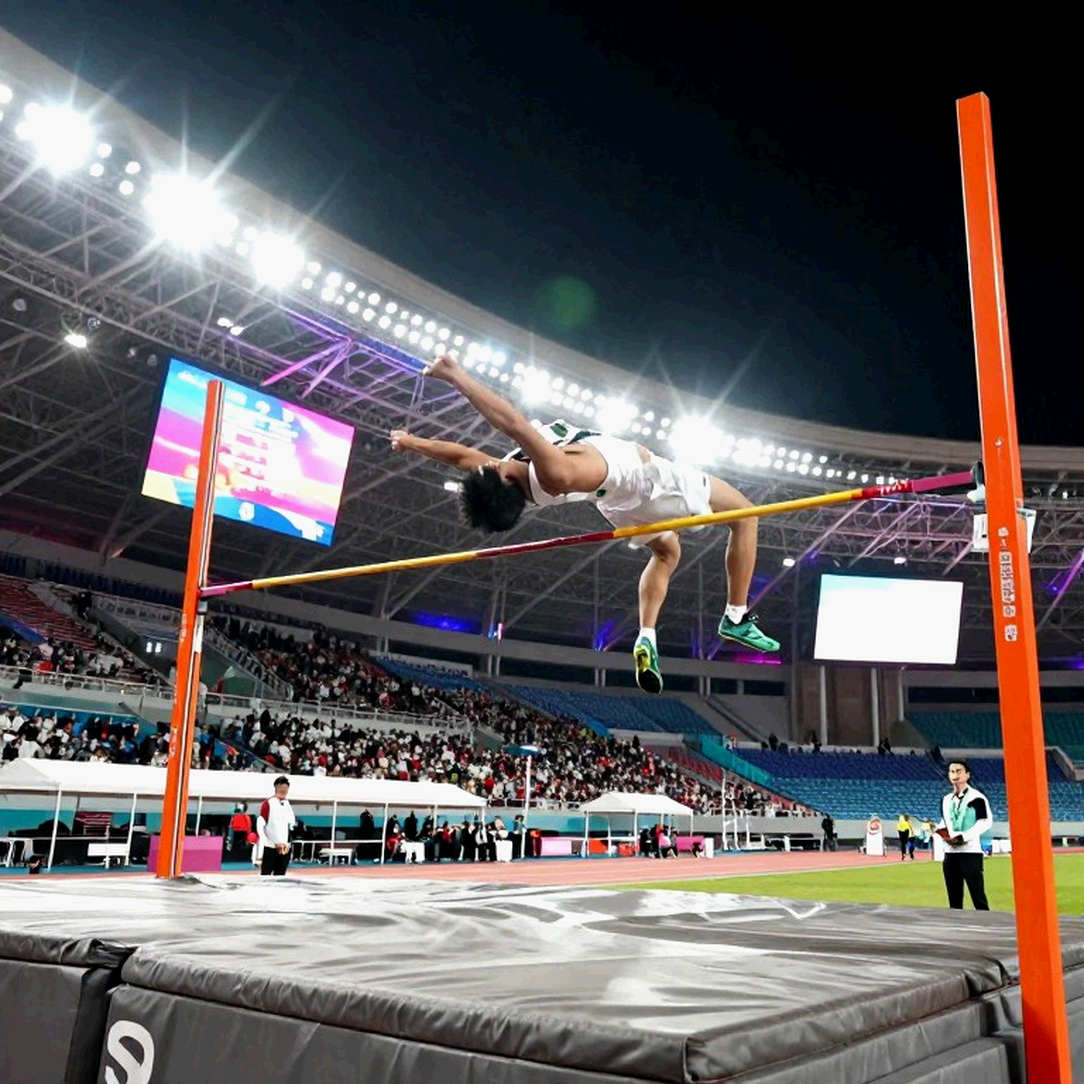
The fourth tool is peaking signals. Cross-check the competition calendar against results: if an athlete runs a season best at a minor meet three weeks before the main championship, that is a bad signal, not a good one. Training cycles have structure, and peaking at the wrong moment is a coordination error, not an achievement.
The stadium had no spectators, but the numbers were still full of noise.
In 2026, when the pandemic suspended the J-League for four months, I was a journalism student in Osaka and could not go to Yodoko Sakura Stadium to watch Cerezo Osaka. I built a self-made dataset from old match video, logging 1,240 pressing situations from Cerezo's 2026 season to calculate PPDA, the number of passes a team allows the opponent before pressing. From that dataset I predicted Cerezo would drop in form when the league returned because they would lack home crowd support, and I placed them second in my forecast table. They finished fourth. I was wrong.
What I did next mattered more than the error. I did not blame luck. I traced the input data back and found I had omitted a variable: crowd influence does not sit only in noise, it sits in referees' decision tempo and in players' psychology during the first ten minutes. I added that variable to the model.
I collect mistakes, classify them, and then I know where a team is heading.
Competition Structure and the Two Doors into the Draw
The third dimension is competition structure and the qualification mechanism. This is the part fans skip most often, and the part that decides most often whether an athlete stands on the start line at all.
In modern athletics there are two routes into a major championship. The first is achieving the qualifying standard within the stated window. The second is accumulating world ranking points, calculated from a tiered competition system. The two routes are not mutually exclusive, and for many athletes they complement each other.
The competition hierarchy can be pictured in four tiers. Tier one is the Olympic Games and the World Championships. Tier two is the Diamond League series and continental championships. Tier three is the Continental Tour and national trials. Tier four is the large road-racing circuit, which runs on entirely different logic: there, entry is bought with performance and prize money, and the ranking system plays no decisive role.
Each tier has its own risk structure. The most notable is the United States selection model: a single meet decides the entire team. Under that model, a reigning world champion can miss the team by losing on the wrong day. This is a structural risk category that only becomes visible once the athlete's nationality and the competition name are known, and it is the clearest example of why athletics analysis cannot be separated from institutions.
Another mechanism to account for is the limit of three athletes per country per event at major championships. This limit creates what I call the domestic vortex effect: in strong nations, the selection meet is harsher than the final. The fourth-place finisher at a national trial may hold a mark better than the bronze medal at the main championship, and still stay home.
A championship slot is a market, and in that market numbers buy more than reputation.
For Vietnamese athletics, this two-tier structure shows most clearly in the distance between the regional stage and the continental stage. At the SEA Games, a gold medal can come from a mark that at the Asian Championships is only enough for a final, and at the world level only enough for a qualifying round. Bui Thi Thu Thao, Nguyen Thi Oanh and Nguyen Thi Huyen are the names that have shaped Vietnam's domestic and regional athletics map for years. But that map does not translate directly into the world map, and any analysis that equates the two is misreading the competition structure.
This also means that when analysing a Vietnamese athlete's mark, the first question is not whether the mark is good, but at which tier it was set, under what selection pressure, and towards what objective.
The Landscape and the Signs of a Generational Handover
The fourth dimension is the event landscape and the balance of power between nations.
Methodologically, the landscape of an event can only be classified with at least the season's top ten marks in that event plus the world lead. From that list, four types emerge: absolute dominance by one athlete; a two-horse race; an open field with many contenders; and a generational transition phase.
The fourth type is the hardest to spot and the one that generates the most forecasting error. The signal is not the highest mark but the age structure of the leading group. If four of the season's top five are over 30 and nobody under 24 sits in the top 20, that event is heading into a generational gap. Inside that gap, the world lead can hold steady for two seasons, then fall sharply when the older generation retires.
The reference structure of world athletics has been fairly stable for decades. Men's and women's sprints lean towards Jamaica and the United States. Middle and long distance events lean towards Kenya and Ethiopia. Men's throwing and pushing events have depth in Europe and the United States. Race walking and women's throwing events are the area where China has built a systemic position. Su Bingtian's 9.83 in the men's 100 metres semi-final at the Tokyo 2026 Olympic Games is a continental milestone. Gong Lijiao in the women's shot put is a multi-year performance cycle, not a single moment.
A methodological point deserves attention: these reference structures are background knowledge. They are not permitted to insert themselves automatically into a specific analysis when that analysis does not mention them. I have seen articles about a regional long jump event padded with a paragraph on Chinese race walking simply because the author had the data in their head. That is the mark of unanchored analysis.
Data does not create stories; it strips the cover off other people's stories.
Rules, Anti-Doping and the Gap That Must Not Be Read as Clean
The fifth dimension is rules and anti-doping. This is the dimension where I place my strongest warning.
There are four governance tiers in athletics: World Athletics as the sport's governing body; the World Anti-Doping Agency as the standard-setter; continental federations; national federations and organising committees. A specific incident can only be analysed once it is known which tier it falls under.
Within the doping category, my framework screens four signal types. The first is an anomaly on the athlete biological passport, in operation since around 2026, tracking blood and urine markers over time. The second is a whereabouts failure, meaning an athlete was not present at a location they had declared to testing authorities. The third is the ten-year sample storage and retrospective re-analysis mechanism, which leads to medals being stripped and reallocated years later. The fourth is an association with a coach or doctor previously sanctioned.
Alongside doping sits the technical rules group. From 1 January 2026, World Athletics applied a zero false start rule: a single false start means disqualification. In the 4x100 metres relay, the exchange zone was extended into a thirty-metre zone from 2026. In jumping and throwing events, the number of invalid trials directly determines placing. In the pole vault, pole specifications must fall within the limits set by competition rules. Each of these rules can turn a medal into a technical footnote.
And here is the single most important point in this entire dimension.
When an analysis contains no doping-related fact whatsoever, the correct output is unassessed. It must not be output as no risk.
This is a basic logical error that nonetheless appears with worrying frequency. In logic, failing to find evidence for a proposition does not equal finding evidence for its negation. In sports practice, an empty doping dataset is routinely presented as a clean bill of health, particularly in tributes to athletes. I have read such pieces, and they share one feature: not a single line states the data source.
A null result is only a null result. It is not a certificate.
The Training System and the Trap of Imported Standards
The sixth dimension is team and training system. It requires the first layer to supply coach names, training group, training base, development programme type, support-staff configuration and any recent personnel change.
At the macro level, world athletics runs on four different training models. The state professional-team model, most typically in China, ties an athlete to a national training centre and a centrally designed training cycle. The collegiate model, most typically in the United States, places athletes inside a school system with a dense competition calendar and scholarship funding. The East African altitude model, with centres such as Iten and Eldoret, turns geography into part of the lesson plan. The Jamaican school model, where school competitions serve as the national talent pipeline.
In Japan, the most notable model is the corporate team system, running in parallel with the ekiden circuit. A Japanese track athlete graduating from university usually joins a corporate team, competing while holding a position within the parent company. That system produces a dense data infrastructure: every training session has a recorder, every race has split data, every athlete has a year-by-year file.
Because I work inside that environment, I have to set a guardrail for myself. Japanese athletics statistical standards must not be applied wholesale to a context without the same data infrastructure.
The distance lies in three places. The first is measurement density: when a system has a recorder at every session, a metric can be computed weekly; when it does not, the metric can only be computed per competition, and the number of data points falls below what time-series analysis requires. The second is squad continuity: the corporate system keeps athletes for years, whereas elsewhere athletes change coaches frequently, bending the progression curve through methodological change rather than ability change. The third is competition culture: in some sporting nations athletes are allowed to empty the tank at a regional meet, while in others a regional meet is only a stepping stone.
The imported-standard trap is not confined to athletics. There was a period when football analytics metrics were transplanted directly from Europe to Southeast Asia without adjustment, and the result was reports praising teams for metrics that meant something entirely different in the original context. When a metric is built on condition A and used in condition B, the first task is to check whether condition B contains the variables the metric assumes.
The Risk Matrix and the Risk Nobody Flags
The seventh dimension is the risk matrix. In my framework, risk splits into categories: competitive risk, doping risk, structural risk, personnel risk, and one category I consider the most important in this context, data risk.
Competitive risk is the chance a rival overtakes at the wrong moment. Doping risk is the chance a result is annulled years later. Structural risk is the chance an athlete is good enough but has no slot because of national limits or a single-meet selection model. Personnel risk is the chance a coach leaves or an athlete changes training groups. All four have clear inputs and can be assessed when information exists.
Data risk is different in nature. It is not the athlete's risk but the conclusion-maker's risk. It appears when an analysis is read as a verdict while it is in fact a to-do list.
An analysis with ten empty cells and one filled cell is not an analysis that is eleven parts complete. It is one part complete, and the rest is debt.
What makes data risk alarming is that it propagates. The first reader misunderstands, the second writer cites, the third builds a model on that citation. Three years later, a false conclusion has a source trail. And in sport, a false conclusion with a source trail can affect contracts, qualifying slots, and a person's name.
The Contrarian Angle: Gaps Always Get Filled, the Question Is With What
Sports analytics carries a tacit belief that a data gap is neutral. That missing data is a neutral state, harmless, merely to be filled in later.
Operationally, the opposite holds.
A gap does not exist in a neutral state. A gap carries pressure. The writer has a deadline, the reader has a decision, the coach has a line-up to pick, and inside that chain of pressure every gap is filled with the most available material, not the most correct material. The most available material is always the story currently in fashion.
I have to test this in my own work. In 2026, working as a contributing writer for an online football magazine during the winter transfer window, I analysed data on more than 200 players moving from the J-League to Europe and computed a correlation coefficient of 0.67 between kilometres run per match and success rate in the Bundesliga. I contacted a scout at a German club and recommended midfielder Ao Tanaka, who was running 11.8 kilometres per match, the highest in the J-League at that time. He joined Fortuna Düsseldorf on loan. My article was cited on several overseas forums.
The 0.67 coefficient is a correlation. It does not say that running more produces success. It says that in a sample of two hundred, two variables tend to move together. An article using that coefficient to declare that high-running players will succeed has turned correlation into causation. And the dangerous part is that such a claim still has a number behind it, so it looks very solid.
The empty analysis I opened this piece with belongs to the same family as that error, only in a more extreme form. Every probability hides a shock; I only make sure it does not repeat.
With an empty file, the shock is not in forecasting wrongly. The shock is in forecasting without knowing what is missing.
What to Demand Before Trusting an Athletics Analysis
I close with the checklist I use for myself, and I suggest readers use it on others.
First, demand the mark with absolute units. If an analysis discusses a breakthrough without a specific mark, that analysis has not begun.
Second, demand the wind reading for sprint and jump events. Without a wind reading there is no record, only a run.
Third, demand the venue altitude. Venues above 1,000 metres must be stated, and every comparison with sea-level marks must be adjusted.
Fourth, demand the qualification channel. A mark meeting a standard and a slot won through world ranking are two different stories about pressure and about scheduling.
Fifth, demand the source date. Every fact about selection, rules and performance has an expiry date.
If any of these five is missing, the analysis belongs in the draft category. Reading a draft is advisable. Trusting a draft is not.
And there is one more thing I want to remind myself of every morning, before opening a new data file. When an empty cell appears, the correct reflex is neither to fill it nor to skip it. The correct reflex is to record precisely that it is empty, to record what it needs in order to be filled, and to leave it exactly as it is until real data arrives.
In athletics, people measure to the hundredth of a second. In athletics analysis, people should hold an equivalent standard. An empty cell correctly recorded is an empty cell that already has value.